Planner, Binder, Executor: Contracts for Safe AI Game Agents
A contract-level guide to separating language planning, deterministic candidate binding and authoritative execution in a shared MMORPG.
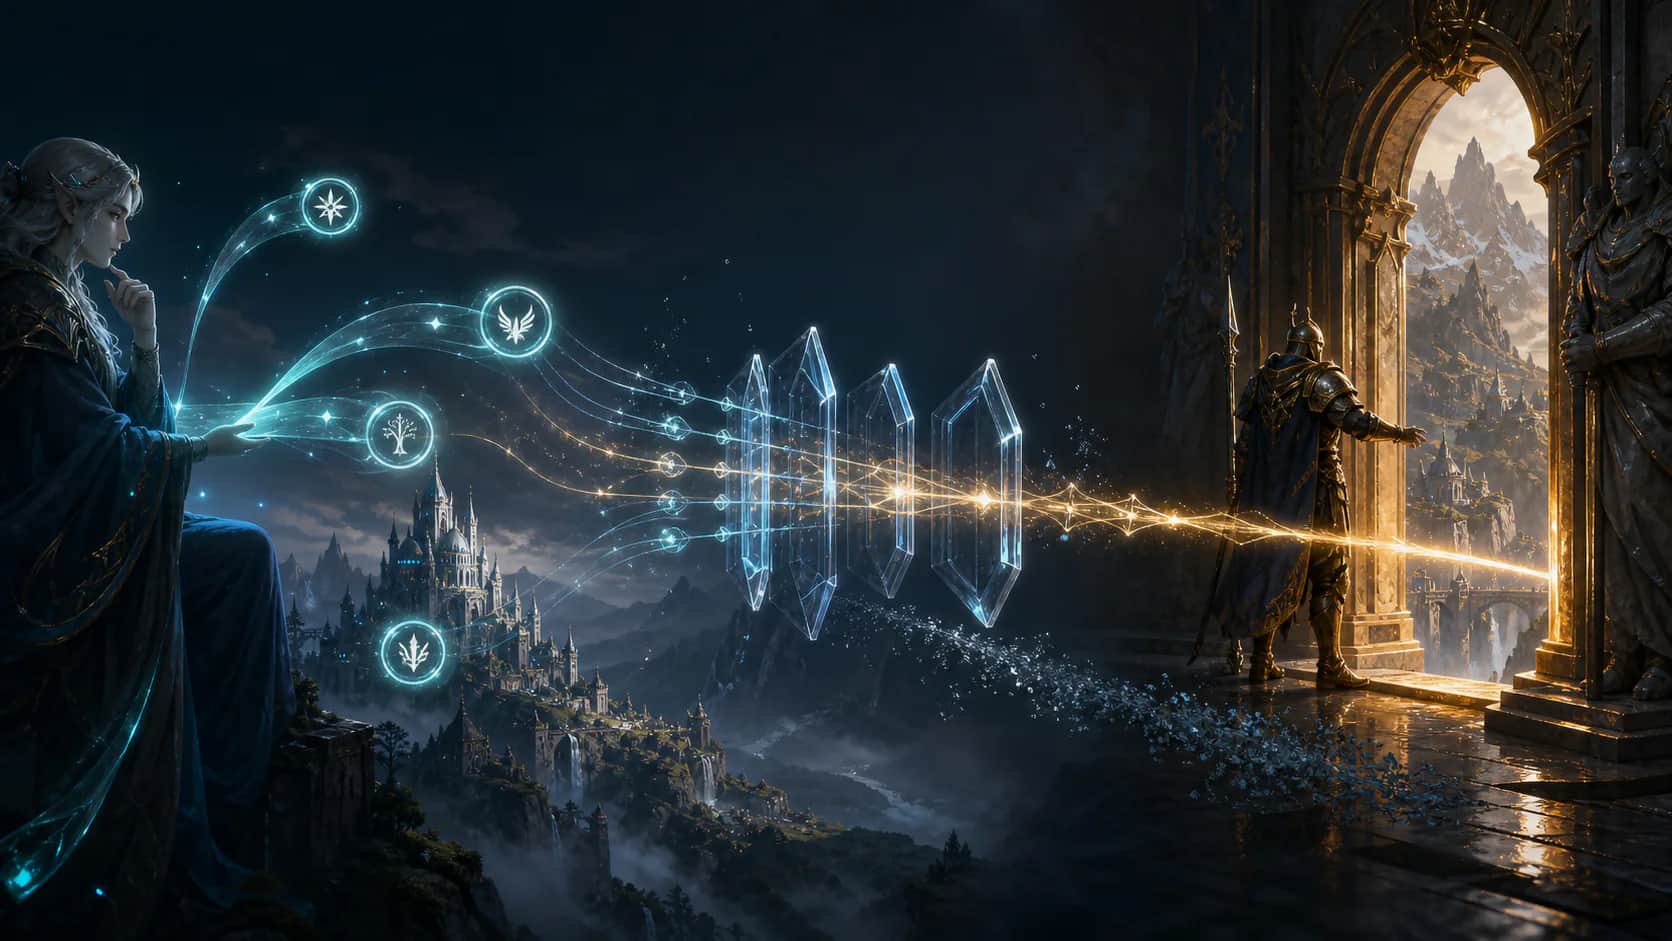 Original editorial visual · Lineage2AI
What this reference establishes
- The planner can interpret goals and propose bounded tool use without owning the environment's execution authority.
- Deterministic binding confines model output to active capabilities, addressed actors, authoritative candidates and server-owned fields.
An AI companion can understand a sentence such as “take me to the nearest weaponsmith, but stop if we enter combat.” Understanding that request is not the same thing as having permission to move a character, choose a destination or change a shared world.
A robust agent architecture separates those jobs into three responsibilities: the planner proposes meaning, the binder converts that proposal into a current authorized request, and the executor alone applies a legal result.
This planner–binder–executor pattern is useful anywhere an LLM can affect persistent multiplayer state. It preserves the creative strength of language models without treating generated output as game truth. The broader server-authoritative AI reference explains why that boundary matters; this page focuses on the three handoff contracts that enforce it.
One player request, three different jobs
Imagine a player asks a companion named Mira: “Use Wind Walk on me and then guide me to the gatekeeper.”
The planner interprets the sentence. It recognizes two goals, their order and the intended speaker. It may select a movement-buff capability and a nearby-destination capability from the bounded choices supplied for this turn. It can also prepare natural speech for success or failure.
The binder does not reason creatively about what the player “probably meant.” It checks that Mira is one of the addressed actors, that each selected capability was actually exposed, and that the chosen skill or destination belongs to the supplied candidate set. It attaches server-owned values such as actor identity and state revisions. If a proposed candidate was invented or belongs to another context, binding fails.
The executor then asks the live game rules whether the actions are still legal. Mira may have died, entered a cooldown, moved too far away or received a newer command while the model was thinking. Only a successful authoritative result may change the world.
The three layers answer different questions:
- Planner: what does the player want?
- Binder: does this proposal refer to exactly the authorized actors, capabilities and candidates from this turn?
- Executor: is the bound action legal in the world now, and what actually happened?
Planner — meaning. It receives the bounded conversation, relevant state and active capability descriptions. It produces semantic action proposals and conditional speech, and it must ask for clarification when the request cannot be resolved safely.
Binder — exact authority. It receives the model proposal together with the original authoritative turn envelope. It produces ordered actions with server-owned identity, candidates and revisions, and it rejects invented candidates, escaped actors, inactive capabilities and model-written authority fields.
Executor — world truth. It receives a bound action together with current world state. It produces a typed success, failure, stale or duplicate outcome, and it rejects illegal, expired, repeated or no-longer-authorized side effects.
Combining those questions inside one probabilistic model makes the system harder to inspect and easier to over-trust.
The planner should choose meaning, not internal authority
The ReAct paper describes an agent pattern that interleaves reasoning with actions and observations. That loop explains how a model can decide what to try and then learn from the environment’s response. It does not require the model to own the environment’s authority.
For a game agent, the planner should receive a bounded view: the addressed companions, the relevant facts, and only the capabilities available in the current turn. Candidate-heavy details can be retrieved only when the request needs them. A model may choose an opaque candidate handle, but it should not invent raw object IDs, database keys, unrestricted coordinates or arbitrary method names.
The Model Context Protocol 2026-07-28 tools specification gives tools explicit names and input schemas while also recommending human oversight for tool invocation. It says servers must validate tool inputs and implement access controls, while clients must treat tool annotations as untrusted unless they come from trusted servers. The broader lesson is important: a structured tool description helps communication, but authority still belongs to the surrounding system.
This is first-party documentation from the Lineage2AI project. In the current source contract, the stable planner prompt and canonical tool catalogue are separate from internal game identifiers. The context compiler supplies a digest for that catalogue, and the active capability slice is intersected with authority supplied by Java. These are SOURCE observations. They do not by themselves prove a running game session.
The binder is a deterministic authority boundary
A schema-valid plan can still be unsafe. It can name a capability that was not active, select the wrong companion, reuse a stale destination or attempt to set a field that should belong to the server.
The binder closes that gap with deterministic checks. It matches capability IDs against the active manifest, confines actors to the addressed party, verifies actor capabilities and restores server-owned arguments. A destination name, for example, must identify exactly one authoritative row before the binder restores its opaque candidate ID. The model cannot override that server-bound field.
This is more than input sanitation. The binder preserves the relationship between a proposal and the snapshot that made the proposal meaningful. Interaction, party, actor and target revisions travel with the planned action. A mismatch becomes a rejection, not an opportunity for the model to improvise a newer reality.
Current Lineage2AI unit tests include successful binding of real opaque candidates and rejection of fabricated or model-overridden candidates. On 2026-09-01, the complete Agent Engine unit command passed 133 tests. That is OFFLINE evidence for the tested contracts, not BOOT, IN_GAME or SOAK evidence.
The executor owns world truth
OWASP’s 2026 Excessive Agency guidance recommends minimizing tool permissions and applying complete mediation: authorization must be enforced in logic, at an independent policy point or in the downstream system instead of being delegated to the LLM. In a shared MMORPG, player text, retrieved content and model output must never be able to expand gameplay permission.
The executor therefore rechecks the preconditions that matter to the side effect. The current Java acceptance contract compares turn correlation, command epoch, revision state, deadline and action preconditions. Its action-outcome schema identifies the authority as L2_JAVA_GAMESERVER. A failed check produces a typed rejection or stale result; persuasive model text cannot convert it into success.
Execution must also be protected from duplicate delivery. A stable idempotency key lets the authority recognize a replay instead of applying the same mutation twice. Reservation occurs only after validation in the inspected acceptance simulator. Again, this is SOURCE evidence for the contract and OFFLINE evidence where local tests exercise it. It is not a claim that every game subsystem has passed live acceptance.
The result must return to the agent
An agent loop is incomplete if it only sends commands outward. The authoritative outcome has to become the next observation.
Suppose Mira planned to cast Wind Walk, but the executor reports that the target changed. The truthful response is not “Done.” The companion can explain that the target moved, ask the player to select themselves again, or remain silent according to policy. The system learns from what happened, not from what the planner predicted would happen.
Lineage2AI’s inspected terminal path finalizes a turn from an authoritative result and releases only model-authored speech whose condition matches that result. The same boundary protects later memory: a proposed fact should not become durable merely because it appeared in a draft plan.
This result-first design extends authoritative-result speech and server-authoritative AI into a complete agent loop.
Evidence boundary
The current package can support SOURCE claims about inspected contracts and OFFLINE claims about the named local test runs. It cannot support BOOT, IN_GAME or SOAK claims. It does not establish provider uptime, live client behavior, every GameServer executor, audible TTS or long-run stability. Those remain separate verification gates.
A practical review checklist
Before connecting an LLM planner to a shared game, ask:
- Can the planner select only the actors and capabilities exposed for this turn?
- Are internal IDs replaced with bounded opaque candidates?
- Which fields are model-writable, and which are restored by deterministic code?
- Does the bound action carry the revisions needed to detect stale state?
- Does the executor recheck legality immediately before every side effect?
- Can duplicate delivery apply a mutation twice?
- Does success-confirming speech wait for the authoritative outcome?
- Are SOURCE, OFFLINE, BOOT, IN_GAME and SOAK results reported separately?
The architecture succeeds when the planner can be imaginative and occasionally wrong while the world remains consistent. The model supplies interpretation. The binder supplies exactness. The executor supplies truth.
Evidence ledger
Primary references and technical sources
- 01
Research PaperPrimary
ReAct: Synergizing Reasoning and Acting in Language ModelsarXiv / ICLR 2023 · accessed 2026-09-01 - 02
Technical SpecificationPrimary
Model Context Protocol 2026-07-28: ToolsModel Context Protocol · accessed 2026-09-01 - 03
Security GuidancePrimary
OWASP GenAI LLM Top 10 2026: Excessive AgencyOWASP GenAI Security Project · accessed 2026-09-01
Lineage2AI evidence promise
Architecture is not deployment proof.
SOURCE, OFFLINE, BOOT, IN_GAME and SOAK remain separate. A planned capability or laboratory result is never presented as live-world evidence.